NexCore NexCore

7 Tips for Choosing an AI Training Server Manufacturer

Time:2026-10-09 Author:Sophia
0%

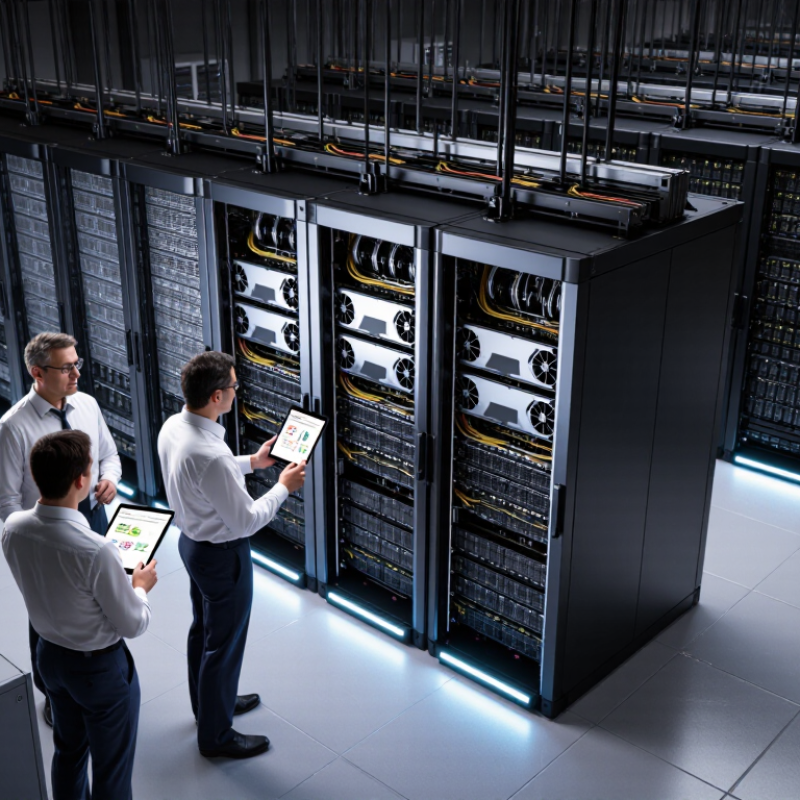
Selecting an ai training server manufacturer is a technical decision with long-term financial consequences. A server may look impressive on paper, yet perform poorly under sustained workloads. Experienced buyers examine GPU compatibility, memory bandwidth, storage speed, and networking latency together. A powerful accelerator cannot compensate for weak cooling or unstable power delivery. Small details matter. Fan noise, rack depth, cable routing, and service access affect daily operations.

Reliable manufacturers provide measurable evidence, not only polished product brochures. Request benchmark results for the models your team actually trains. Ask whether those tests used identical datasets, batch sizes, and software versions. Review warranty terms, replacement procedures, firmware support, and spare-parts availability. A credible supplier should explain thermal limits clearly and identify potential bottlenecks before installation. Independent certifications and documented quality controls also strengthen confidence. Speak with existing customers when possible. Their experience may reveal support delays that sales calls conceal.

Cost remains important, but the cheapest quotation can become expensive after repeated downtime. Evaluate total ownership costs, including electricity, cooling, maintenance, upgrades, and technical labor. Security practices deserve equal attention, especially for sensitive research environments. Some recommendations may not fit every organization. A small laboratory needs different capacity than a national research center. No checklist is flawless. That is why the final choice should combine verified specifications, practical demonstrations, and careful conversations with engineers. A thoughtful ai training server manufacturer will welcome difficult questions and admit where its platform has limitations. That honesty is often more valuable than another impressive performance number.
7 Tips for Choosing an AI Training Server Manufacturer

Define Training Needs with 80 GB H100 Memory and 700 W GPU TDP

7 Tips for Choosing an AI Training Server Manufacturer

Define Training Needs with 80 GB H100 Memory and 700 W GPU TDP

An 80 GB H100 GPU can handle large models, but memory alone does not define your server needs. Measure model size, batch size, sequence length, and expected training frequency. A manufacturer should translate these figures into GPU count, interconnect design, storage speed, and cooling capacity.

The 700 W GPU TDP demands careful engineering. Ask for measured power usage, not only maximum ratings. Check whether the power supply supports sustained GPU loads, startup surges, and future expansion. Inspect airflow paths, fan control, heatsink clearance, and rack temperature limits. Small design flaws become visible during overnight training.

Thermal evidence matters. Request burn-in reports, noise data, and performance results under continuous workloads. Confirm that the system maintains stable clock speeds without frequent throttling. I once focused too heavily on accelerator specifications. That assumption was wrong. The server became unstable when several GPUs trained together. A reliable manufacturer should provide configuration records, firmware guidance, replacement procedures, and responsive technical support. Also ask how the company validates memory errors and monitors power delivery in production. These details may appear ordinary, yet they often separate a usable training platform from an expensive experiment.

Evaluate Multi-GPU Scaling Through 900 GB/s NVLink Bandwidth

7 Tips for Choosing an AI Training Server Manufacturer

Tip 1: Verify the 900 GB/s NVLink claim carefully.

Ask whether it describes total bandwidth, per-GPU bandwidth, or bidirectional throughput. Request topology diagrams, measured benchmarks, and test conditions. A specification alone proves little.

Tip 2: Examine multi-GPU scaling with real workloads.

Eight GPUs may look impressive, yet performance can drop when models exchange gradients. Ask for results using transformer training, large batches, and mixed-precision computation. Check communication overhead, memory utilization, and scaling efficiency. Watch the graphs.

Tip 3: Inspect the server physically and operationally.

High-speed interconnects need stable cooling, clean cable routing, and reliable power delivery. Ask how technicians replace GPUs without disturbing neighboring connections. Also review firmware updates, diagnostic tools, and response times for support. My experience is that small service delays become expensive during long training runs.

Do not accept a perfect benchmark without context. Results may change with software versions, dataset size, or thermal limits. Require a repeatable acceptance test before purchase. The manufacturer should explain failures, not only advertise peak numbers. A useful test might compare one, four, and eight GPUs while recording throughput, latency, temperature, and power consumption. This evidence reveals whether 900 GB/s bandwidth improves training or merely strengthens the specification sheet.

Verify Cooling Capacity Against 700 W GPU Heat Loads

Choosing an AI training server manufacturer starts with cooling, not processor speed. A 700 W GPU releases nearly 700 W of heat under sustained load. Eight GPUs can therefore produce about 5.6 kW, before accounting for CPUs, memory, storage, and power losses. ASHRAE TC 9.9 recommends server inlet temperatures around 18–27°C for common data-center classes. Ask manufacturers to show measured inlet temperatures at full training load, not idle conditions.

Tip 1: Request a thermal test report. It should include GPU utilization, room temperature, airflow, fan speed, and rack density. Look for hotspot data, because average temperature can hide one overheated accelerator. The IEA’s Electricity 2024 report estimated global data-center electricity use at roughly 460 TWh in 2022. Cooling efficiency deserves serious attention as workloads expand.

Tip 2: Verify cooling capacity per rack. A manufacturer claiming “high-density ready” should specify air cooling limits, liquid-cooling compatibility, coolant flow, and failure alarms. Tip 3: Check performance after filter loading and partial fan failure. Real facilities are imperfect. A design that passes a laboratory test may struggle beside a warm aisle or blocked floor tile. Request independent commissioning records, service response times, and temperature alarms that operators can actually review. Some specifications look impressive, but missing test conditions should make buyers pause.

7 Tips for Choosing an AI Training Server Manufacturer — Verify Cooling Capacity Against 700 W GPU Heat Loads

How to read this chart: Each high-performance GPU is modeled at a 700 W heat load. The recommended cooling capacity includes a 15% thermal headroom to accommodate sustained workloads, airflow variation, filter loading, and ambient-temperature changes. Confirm that a manufacturer’s continuous cooling rating—not only its peak rating—meets or exceeds the recommended value.

  • Verify the continuous cooling capacity per GPU.
  • Check whether the rating applies at the intended ambient temperature.
  • Allow thermal headroom above the nominal 700 W GPU load.
  • Review airflow paths, fan redundancy, and serviceability.
  • Confirm cooling performance for the complete server, including CPUs, memory, storage, and power supplies.
  • Request sustained-load test results rather than short benchmark measurements.
  • Ensure monitoring supports temperature, fan speed, and thermal-throttling alerts.

Compare Power Efficiency with the 1.56 Average Data-Center PUE

7 Tips for Choosing an AI Training Server Manufacturer

Choosing an AI training server manufacturer involves more than GPU density or advertised throughput. Power efficiency deserves equal attention, especially when training jobs run for days.

A useful reference is the reported average data-center PUE of 1.56. PUE means total facility energy divided by IT equipment energy. A PUE of 1.56 means 1.56 units enter the facility for each unit reaching computing hardware. It is a benchmark, not a guarantee.

Ask the manufacturer for measured server power at idle, typical training load, and peak demand. Request rack-level data, not only component specifications. A server drawing 8 kW may appear efficient, yet cooling and power-conversion losses can raise operating costs.

Compare complete energy use per training task, including failed runs and data movement. Small details matter. Fan curves, airflow paths, efficient power supplies, and workload-aware controls can change results.

In practice, test identical systems with the same dataset, software stack, and ambient temperature.

Reliable suppliers should explain test equipment, sampling time, and calculation methods. Independent validation is valuable, but transparency matters more than polished charts.

Ask whether the quoted PUE reflects a modern facility or an older site. This point is often overlooked. A low server power figure cannot offset poor cooling design. Nor can a strong benchmark erase unstable performance.

Record real monthly energy bills after deployment. The first estimate may be wrong. That is useful evidence, not failure. Choose a manufacturer that shares limitations, supports firmware tuning, and measures efficiency after installation.

Audit Reliability, Support, and Lifecycle Planning for 3–5 Years

Tip 1: Audit reliability before comparing prices. Ask the manufacturer for burn-in procedures, failure-rate records, and thermal test results. A serious supplier should explain how servers perform under sustained AI workloads. Request references from facilities operating similar systems. One polished demo proves little. I learned that hard way.

Tip 2: Examine support as a three-to-five-year commitment. Confirm response times, escalation paths, remote diagnosis, and onsite repair coverage. Ask whether technicians keep local spare parts, including power supplies, fans, memory, and accelerators. Read warranty exclusions carefully. A fast reply is not the same as a useful repair. Test the support channel with technical questions before signing.

Tip 3: Audit the full lifecycle plan, not only launch performance. Check firmware update schedules, operating-system compatibility, replacement-part availability, and upgrade options. Confirm rack dimensions, power draw, cooling requirements, and future capacity limits. A server that fits today may strain your facility next year. Manufacturers should document secure data handling during repairs and equipment returns.

Be skeptical of fixed five-year forecasts. Workloads change, and accelerator demand may grow faster than expected. Build an annual review point into the contract. Include measurable service targets and written maintenance responsibilities. Some details may remain uncertain, but vague promises deserve written clarification. Reliability is experienced over time, not declared in a brochure.

7 Tips for Choosing an AI Training Server Manufacturer - Audit Reliability, Support, and Lifecycle Planning for 3–5 Years
Tip Evaluation Dimension Why It Matters Practical Acceptance Benchmark 3–5 Year Planning Check
1 Manufacturing Quality and Auditability Consistent assembly, traceability, and documented quality controls reduce configuration errors and improve repeatability across server batches. Quality-management certificates, factory-audit reports, serial-number traceability procedures, incoming-component inspection records, and final-test checklists. Pass condition
Every delivered system should have a documented bill of materials, serial traceability, burn-in or functional-test results, and a defined nonconformance process.
Confirm that quality records remain available for the full warranty period plus the expected operational life of the system.
2 Reliability and Thermal Engineering AI training creates sustained high power and thermal loads. Inadequate cooling can cause throttling, instability, component wear, or unplanned downtime. Thermal-test results, airflow diagrams, power-budget calculations, environmental operating limits, fan-control policies, and failure-rate definitions. Pass condition
The proposed configuration should operate within published temperature, humidity, airflow, and power limits at sustained training load, not only during short benchmarks.
Include expected increases in model size, utilization, ambient temperature, and electricity capacity when sizing racks, cooling, and power distribution.
3 GPU, CPU, Memory, and Network Compatibility Training performance depends on balanced compute, memory capacity, storage throughput, and interconnect bandwidth. A bottleneck in one subsystem can limit the entire cluster. Validated configuration matrix, supported accelerator and processor combinations, PCIe or equivalent lane allocation, memory population rules, network topology, and storage test results. Pass condition
The manufacturer should provide a written compatibility list and demonstrate that the selected configuration supports the intended framework, operating system, drivers, and communication libraries.
Reserve expansion capacity for additional memory, storage, networking, or accelerator modules where the chassis, power supply, cooling, and motherboard design permit it.
4 Acceptance Testing and Performance Transparency Transparent testing helps distinguish theoretical specifications from repeatable performance under the organization’s actual workloads. A mutually agreed acceptance-test plan, workload scripts, dataset assumptions, software versions, power limits, ambient conditions, and raw performance logs. Pass condition
Results should be reproducible, use clearly defined metrics, and identify whether performance is measured per server, per accelerator, or across the complete cluster.
Record baseline results before production deployment so future firmware, driver, and hardware changes can be compared against a known reference.
5 Warranty, Service-Level, and Spare-Parts Support A failed accelerator, power supply, fan, memory module, or storage device can interrupt expensive training jobs and delay project milestones. Warranty terms, response and resolution targets, escalation contacts, replacement procedures, repair locations, spare-parts policy, and exclusions for software or firmware issues. Pass condition
Service commitments should define support hours, severity levels, acknowledgement targets, replacement logistics, and responsibilities for on-site access.
Align warranty duration and support availability with the planned 3–5 year operating period; price post-warranty coverage before signing the purchase order.
6 Firmware, Driver, and Security Maintenance Long-lived AI infrastructure requires controlled updates to maintain hardware compatibility, security, stability, and support for evolving software environments. Firmware release policy, security-advisory process, driver-validation procedure, update rollback method, vulnerability-notification channel, and change-management documentation. Pass condition
Updates should be versioned, documented, testable before deployment, and accompanied by compatibility notes for the relevant operating system and accelerator software stack.
Define a maintenance calendar, staging environment, rollback process, and ownership model for updates throughout the expected lifecycle.
7 Total Cost of Ownership and End-of-Life Planning Purchase price is only one part of the cost. Power, cooling, software support, repairs, migration, and asset retirement can materially affect the 3–5 year budget. Three- to five-year cost model covering acquisition, electricity, cooling, support, maintenance, spare parts, software subscriptions, logistics, and decommissioning. Pass condition
Compare at least two lifecycle scenarios using the same workload assumptions, utilization rate, electricity price, support scope, and expected refresh date.
Confirm upgrade paths, product-availability commitments, data-erasure procedures, resale or recycling options, and migration support before the planned refresh.
Recommended decision method: Score each dimension from 1 to 5, assign higher weights to reliability, support, and lifecycle risk, and require documentary evidence before awarding the highest score. Technical specifications should be validated through a workload-specific acceptance test.

FAQS

How should I define training needs before choosing a server?

Measure model size, batch size, sequence length, and training frequency. Then determine GPU count, storage speed, and interconnect needs.

Why does an 80 GB GPU not determine the whole server design?

Memory capacity is only one factor. Large batches, long sequences, and frequent training may require more accelerators and faster data paths.

What power details should I request for a 700 W GPU?

Ask for measured power during sustained workloads. Confirm support for startup surges, continuous loads, and future expansion.

How much heat can multiple high-power GPUs create?

Eight 700 W GPUs can release about 5.6 kilowatts of heat. CPUs, memory, storage, and power losses add more heat.

What should a proper thermal test report include?

It should show GPU utilization, room temperature, airflow, fan speed, and rack density. Hotspot temperatures matter too.

How can I check whether cooling works during real training?

Request full-load inlet temperatures and continuous performance results. Idle measurements are not enough. Overnight testing reveals weaknesses.

What cooling features should a dense training server support?

Check air-cooling limits, liquid-cooling compatibility, coolant flow, and failure alarms. Ask whether blocked airflow affects performance.

How can I detect thermal throttling?

Review clock speeds during long workloads. Stable clocks are encouraging, while repeated drops may indicate heat or power problems.

What happens if a fan fails or a filter becomes dirty?

Ask for test results under partial fan failure and filter loading. Real facilities are imperfect. Laboratory results can mislead.

What support should the manufacturer provide after delivery?

Request configuration records, firmware guidance, replacement procedures, monitoring instructions, and clear service response times. I once trusted specifications too much. That was a mistake.

Conclusion

Choosing the right ai training server manufacturer requires more than comparing processor counts or purchase prices. Start by defining your workloads, model sizes, and expansion plans, then confirm that the system can support GPUs with up to 80 GB of memory and handle thermal demands from 700 W GPU TDPs. For multi-GPU training, evaluate interconnect design and whether the platform can make effective use of up to 900 GB/s NVLink bandwidth without creating communication bottlenecks.

Cooling, power, and long-term operating costs should also guide the decision. Verify that the chassis, fans, liquid-cooling options, and data-center infrastructure can continuously manage high heat loads. Compare power efficiency against an average data-center PUE of 1.56, while considering electricity, maintenance, and space requirements. Finally, audit reliability records, technical support, replacement-part availability, warranty terms, upgrade flexibility, and lifecycle planning for three to five years. A dependable supplier should provide transparent testing, practical deployment guidance, and support that grows with your AI strategy.
Sophia

Sophia

Sophia is a dedicated marketing professional with an exceptional depth of knowledge about her company's products and services. With a keen understanding of market trends and customer needs, she crafts insightful blog posts that not only inform but also engage readers, enriching the company’s online......