NexCore NexCore

China Top 10 Nvidia GPU Server Manufacturers

Time:2026-11-03 Author:Sophia
0%

Choosing a server for artificial intelligence is more complex than counting GPUs. Buyers must consider accelerator availability, power delivery, cooling, networking, and support. A configuration that looks strong on paper can struggle when a dense workload runs for hours. Small details matter, too: rack depth, cable paths, firmware updates, and the time needed to replace a failed fan.

NVIDIA founder and CEO Jensen Huang has said, “Accelerated computing has reached the tipping point.” That shift makes the nvidia gpu server manufacturer an important partner, not merely a hardware supplier. A capable manufacturer should explain how its systems handle real workloads, publish clear configuration details, and help customers plan deployment and maintenance. Still, no single brand fits every data center. Some buyers prioritize validated platforms and local service; others need flexible configurations, short lead times, or specialized cooling. There are trade-offs.

This guide compares ten manufacturers through practical criteria, including GPU platform options, system design, integration experience, and support. It also recognizes a limitation: product specifications and availability can change quickly, so readers should verify current details directly with vendors. A polished brochure is not proof of performance. Ask for workload-relevant test results, clear warranty terms, and specific power and cooling requirements before making a decision.
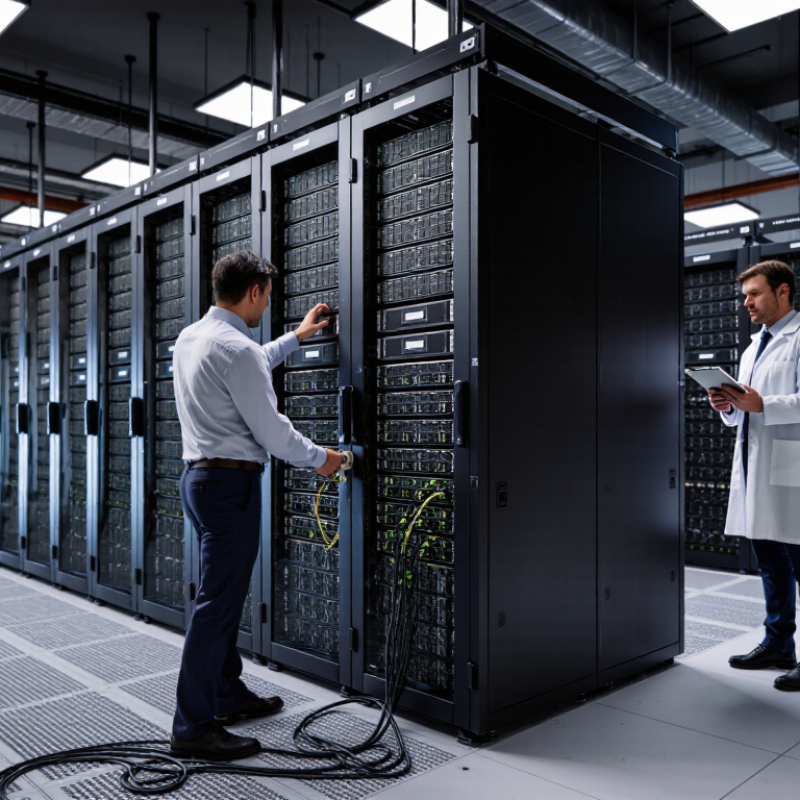
China Top 10 Nvidia GPU Server Manufacturers

What Is an NVIDIA GPU Server and How Is It Used?

An NVIDIA GPU server is a computer designed to handle workloads that benefit from many calculations running at once. It combines one or more graphics processing units with conventional processors, memory, storage, and fast network connections. The GPUs do parallel work; the processors coordinate tasks and manage the system. Cooling and power delivery matter, too. Under sustained workloads, heat builds quickly, and insufficient airflow can reduce performance or interrupt operation.

These servers are commonly used to train and run AI models, analyze large datasets, render images, and simulate scientific or engineering problems. For example, a research team might use a rack-mounted system to process medical images or model fluid movement. Training generally needs substantial memory and fast connections between GPUs, while serving a model may depend more on response time and steady throughput. The right setup depends on the workload. More GPUs do not always mean faster results.

In practice, teams should check GPU memory, software compatibility, network bandwidth, power limits, and the cost of keeping the system cool. A small test using real data can reveal bottlenecks before a full deployment. That matters. Performance figures alone can be misleading, and workload behavior may change as data or models grow. Even a well-specified server can be poorly matched to its users.

How China's GPU Server Manufacturing Industry Is Structured

China’s GPU server manufacturing industry is better understood as a supply chain than as a simple list of manufacturers. System integrators design complete rack configurations, while contract manufacturers assemble boards, chassis, and cabling. Component suppliers provide power units, fans, memory, and network adapters. Each role affects performance and reliability.

The work becomes tangible on the production floor. Technicians check board seating, cable paths, airflow gaps, and power connections before running diagnostic tests. High-density systems may use liquid cooling, but that adds pumps, tubing, and maintenance requirements. Small details matter. A poorly routed cable can restrict airflow or complicate service.

Manufacturers also adapt systems for local data centers, where rack depth, electrical capacity, and cooling infrastructure differ. Some firms focus on standardized configurations; others customize around workload and deployment needs. Buyers should examine test procedures, warranty support, and component traceability, not just peak compute figures. Product documentation can be uneven, and published specifications do not always explain sustained performance. That deserves scrutiny. The industry is capable, but quality control and after-sales service can vary between production batches.

Which Companies Rank Among China's Top 10 NVIDIA GPU Server Manufacturers?

China’s leading GPU-server manufacturers are best compared by engineering depth, not by a simple list. A useful shortlist examines accelerator compatibility, high-speed fabric design, power delivery, cooling, and local service capacity. TrendForce forecast 1.67 million AI server shipments worldwide in 2024, up 41.5% year over year. This growth makes production scale important, but shipment volume alone does not prove reliability. That distinction matters.

A careful ranking should also check validated configurations and sustained-load performance. Ask for test results showing GPU temperatures, power draw, and network throughput during extended workloads. A rack may look capable on paper, yet struggle when several dense systems run continuously. Check spare-part availability and response times in the intended region. Public reports rarely disclose comparable manufacturer-level GPU-server data, so any “top 10” list should explain its criteria and avoid presenting estimates as audited rankings.

Tips: Request a configuration-specific test report, not a generic brochure. Confirm cooling limits, warranty coverage, and delivery lead time in writing. Small details count. A reflective note: published specifications can still miss real operating conditions, so independent testing is worth the extra effort.

How Their Product Lines and Technical Capabilities Compare

China’s leading ten GPU-server manufacturers differ less in headline accelerator counts than in system design. Their product lines generally span compact two- or four-GPU nodes, dense eight-GPU platforms, and rack-scale clusters. Compare memory capacity, high-speed interconnects, and sustained power limits—not just peak performance. That gap matters. A server that fits a standard rack may be easier to deploy, while a denser design can demand stronger cooling and power infrastructure.

IDC’s 2024 Worldwide AI and Generative AI Spending Guide projects global AI spending will reach $632 billion by 2028, growing at a 29% compound annual rate from 2024. That is broad AI spending, not server revenue, but it signals rising pressure on infrastructure. Among manufacturers, technical maturity shows in validated workloads, firmware control, remote diagnostics, and access to replacement parts. Liquid cooling can support dense configurations, yet introduces maintenance demands that product sheets often understate. Not always. A polished specification may conceal differences in tested software stacks or sustained thermal performance. Even this comparison has a blind spot: published benchmarks rarely use identical workloads. Buyers should request rack-level power figures and workload-specific test results before judging capability.

China Top 10 Nvidia GPU Server Manufacturers - How Their Product Lines and Technical Capabilities Compare

Manufacturer names and brands are intentionally omitted. The ten rows below compare representative GPU-server product profiles found in the market; they are not attributed to specific manufacturers and do not constitute a verified manufacturer ranking. Configurations vary by product and generation.

Profile Product class Accelerators per system Typical platform GPU interconnect Cluster networking Cooling and deployment Common workloads
01 Compact workstation 1–2 Tower or short-depth system; usually one CPU socket PCIe; peer-to-peer support depends on platform Standard Ethernet, commonly 10–25 GbE Air-cooled; office or lab deployment Development, visualization, inference, and small-scale model tuning
02 2U inference server 2–4 Rack-mount system; one or two CPU sockets PCIe 10–100 GbE options, depending on configuration High-airflow air cooling; standard data-center rack Online inference, computer vision, and media processing
03 4U general-purpose GPU server 4–8 One or two CPU sockets; multiple PCIe expansion slots PCIe; topology varies with board and riser design 25–100 GbE options Air-cooled; rack power and airflow planning required Mixed AI training and inference, simulation, and rendering
04 8-GPU accelerated compute server 8 Typically a dual-socket, high-power rack server PCIe or a platform-specific high-bandwidth GPU fabric 100–400 Gb/s-class fabric options for cluster use High-capacity air cooling or liquid-cooling options Multi-GPU training, fine-tuning, and high-throughput inference
05 High-memory accelerator system 4–8 Server chassis configured for high-power accelerators Platform-dependent; check GPU-to-GPU bandwidth and topology 100–400 Gb/s-class options in cluster configurations Liquid cooling may be offered for dense deployments Large-model workloads constrained by accelerator memory capacity
06 Dense PCIe expansion server 4–8, subject to slot and power limits Multi-riser rack system with emphasis on PCIe lanes PCIe; not all designs provide a direct GPU fabric 25–100 GbE, with faster adapters available on some platforms Air cooling; verify slot spacing, thermal limits, and power budget Independent inference jobs, video analytics, and virtualized GPU use
07 Storage-rich GPU server 2–4 Rack server with additional drive bays or NVMe capacity PCIe 25–100 GbE options; storage fabric depends on system design Air-cooled; chassis layout balances drive capacity and airflow Data preparation, retrieval workloads, and storage-adjacent inference
08 Liquid-cooled high-density server 4–8 High-power rack system designed for facility cooling integration PCIe or platform-specific high-bandwidth fabric 100–400 Gb/s-class cluster options Direct liquid cooling; requires compatible coolant distribution infrastructure Dense AI compute deployments with constrained rack cooling capacity
09 Cluster-ready training node 8 per node is a common design target Compute, management, and high-speed network interfaces integrated for cluster use Depends on accelerator platform; validate collective-communication topology High-speed Ethernet or another supported cluster fabric Air or liquid cooling; requires coordinated rack-level deployment Distributed training and multi-node scientific computing
10 Rack-scale integrated solution Multiple servers; total varies by rack design Coordinated compute, switching, power, and management components Intra-server topology varies; inter-server communication uses cluster networking High-speed fabric selected for the intended cluster scale Rack-level power, cooling, cabling, and serviceability planning required Data-center AI clusters and large-scale model training

Comparison note: Accelerator count, supported interconnects, network speed, and cooling options are platform-specific. Confirm the exact bill of materials, compatibility, thermal design, and validated software support for any system being evaluated.

What Factors Matter When Choosing a GPU Server Manufacturer?

Choosing a GPU server manufacturer starts with workload fit, not the largest specification sheet. Ask for test results using your model size, precision, batch size, and software stack. A server that performs well in a short benchmark may throttle during overnight training. Small details matter. Check accelerator bandwidth, host memory, storage throughput, and whether the chassis sustains rated power under continuous load.


Power and thermal design deserve equal scrutiny. The International Energy Agency’s Electricity 2024 report estimates that data centres used about 460 TWh globally in 2022, with consumption potentially exceeding 1,000 TWh by 2026. That scale makes efficiency more than an operating-cost issue. Request measured power use per workload, inlet-temperature limits, and evidence from full-load testing—not just component figures. Cooling claims can sound tidy on paper.

Evaluate manufacturing quality and support before signing. Ask how component substitutions, firmware versions, and final test records are tracked. Confirm spare-part availability, response times, warranty exclusions, and regional escalation routes. Request a sample acceptance report, then verify that the delivered system matches it. I would also test one node in your own rack; integration surprises still happen, and the first deployment is rarely perfectly smooth. Price matters, but unclear service terms can cost more.

FAQS

How should buyers compare leading GPU server manufacturers?

Compare engineering depth, validated configurations, cooling, power delivery, and regional support. Shipment volume alone does not prove reliability.

What should a credible manufacturer ranking include?

It should explain its criteria and distinguish estimates from audited rankings. Public reports rarely provide directly comparable manufacturer-level data.

Which technical details matter beyond accelerator count?

Check memory capacity, interconnects, sustained power limits, and workload-specific results. Peak performance can hide important gaps.

What tests should buyers request?

Ask for extended-load results showing GPU temperatures, power draw, and network throughput. Use your model size and software stack when possible.

How do dense server designs affect deployment?

Dense systems may need stronger cooling and power infrastructure. A standard-rack design can be easier to install. Not always.

Why should buyers examine energy use?

Data centres used about 460 TWh globally in 2022, according to an energy report. Request measured power use per workload, not just component figures.

What should buyers verify about cooling?

Confirm inlet-temperature limits and full-load test results. Liquid cooling can support dense systems, but it also adds maintenance demands.

Which support details should be confirmed before purchase?

Get spare-part availability, response times, warranty exclusions, and delivery lead times in writing. Check how substitutions and firmware versions are recorded.

Is a manufacturer’s sample test report enough?

It helps, but test one node in your own rack if possible. Integration surprises still happen. Perfect deployment is not guaranteed.

Conclusion

An NVIDIA GPU server is a computing system built to handle demanding workloads such as artificial intelligence training, scientific simulation, data analysis, and high-performance computing. China’s manufacturing industry includes server designers, system integrators, component suppliers, and specialist solution providers. Rather than relying only on product labels, a useful overview of the top ten manufacturers should consider how each type of company brings together processing units, memory, storage, networking, cooling, and software support to create complete systems.

Product lines can differ in GPU capacity, rack density, power efficiency, expandability, and suitability for specific workloads. When evaluating an nvidia gpu server manufacturer, buyers should compare technical specifications alongside reliability testing, customization options, delivery capability, after-sales service, and total operating costs. The right choice depends on the intended applications, infrastructure, budget, and plans for future growth. A structured comparison of these factors helps readers understand the market and identify solutions that fit their computing requirements.

Sophia

Sophia

Sophia is a dedicated marketing professional with an exceptional depth of knowledge about her company's products and services. With a keen understanding of market trends and customer needs, she crafts insightful blog posts that not only inform but also engage readers, enriching the company’s online......